AMD announced on November 24 that, in partnership with IBM and AI startup Zyphra, it has successfully trained ZAYA1, the world’s first large-scale Mixture-of-Experts (MoE) foundation model trained entirely on AMD hardware, after more than a year of collaboration.
According to AMD’s official blog post, ZAYA1 is the first large MoE model built entirely within the AMD ecosystem. The entire training process took place on IBM Cloud, powered by:
- AMD Instinct MI300X accelerators
- Pensando networking technology
- The open-source ROCm software platform
A detailed technical report has been published on arXiv.
To train ZAYA1, the three companies jointly built a massive, highly reliable dedicated training cluster consisting of:
- 128 nodes
- 8 × AMD Instinct MI300X GPUs per node
- A total of 1,024 MI300X GPUs
- Interconnected via AMD Infinity Fabric high-speed links
The cluster delivered real-world training performance exceeding 750 PFLOPs (750 quadrillion floating-point operations per second). Zyphra also developed a highly optimised training framework tailored specifically for the AMD platform to ensure stability and efficiency throughout the process.
ZAYA1 was pre-trained on an enormous dataset of up to 14 trillion tokens, utilising a staged curriculum-learning approach that gradually transitioned from unstructured web text to higher-quality, information-dense data related to mathematics, coding, and reasoning.
Benchmark results show that ZAYA1’s overall performance is on par with the industry-leading Qwen3 series and surpasses mainstream open-source models such as SmolLM3 and Phi4. Remarkably, even without task-specific instruction tuning, the reasoning-focused version of ZAYA1 already approaches the performance of specialised Qwen3 variants on complex math and STEM reasoning tasks.
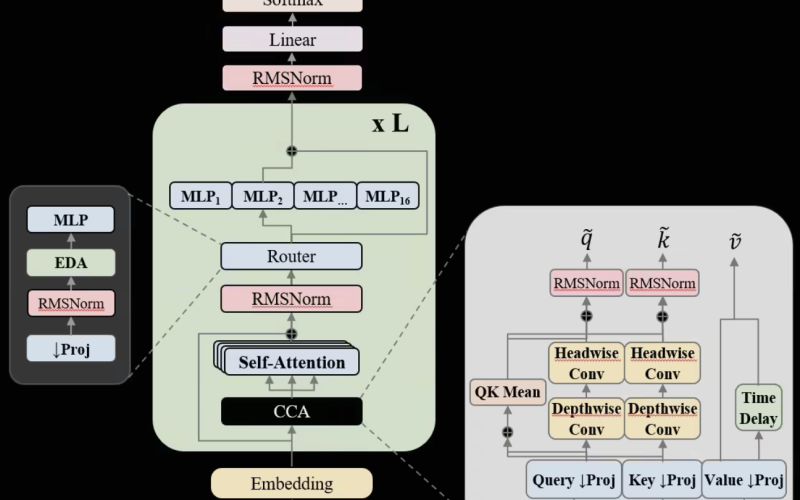
ZAYA1’s strong results stem from two key architectural innovations:
- CCA (Compressive Convolutional Attention): A novel attention mechanism that incorporates convolution inside the attention module, dramatically reducing both compute and memory requirements.
- An improved routing structure for the MoE’s linear router, enhancing model expressiveness and expert specialisation.
These breakthroughs effectively address the computational and memory bottlenecks inherent in traditional Transformer architectures.
Zyphra emphasised that ZAYA1 is just the beginning. The version released today is a base model preview only. The team plans to roll out fully post-trained (instruction-tuned and aligned) versions in the future, along with comprehensive performance evaluations and detailed training insights.
The above content is compiled by ModeZone, a fashion and entertainment magazine.